Cloudflare AI Bot Settings After Sept 15: Check Yours
Cloudflare now splits AI bots into Search, Agent and Training. Here is how to check your settings so AI training is off and Googlebot still gets through.
The short answer
Cloudflare sorts AI crawlers into Search, Agent and Training, and you set each one separately in the Security settings under Configure AI bot policies. Because Googlebot, Bingbot and Applebot count as Training as well as Search, setting Training to Block can also block them. To opt out of AI training but stay in search, set Search to Allow, Training to Disallow and turn on Bot Preference Sync, then check your robots.txt and run a Search Console live test.
Reading options
On this page
Before you start
Cloudflare permission to view and change the zone's Security settings, a saved copy of the current robots.txt file, and a rollback note recording the present Search, Agent and Training choices. Google Search Console access is optional but recommended for a live URL inspection after the change.
If your site sits behind Cloudflare, open your AI bot policies today and check three settings: Search, Agent and Training. For most sites that want to stay in Google and Bing but keep content out of AI training, the right mix is Search on Allow and Training on Disallow with Bot Preference Sync turned on. Training on Block can quietly shut out Googlebot too.
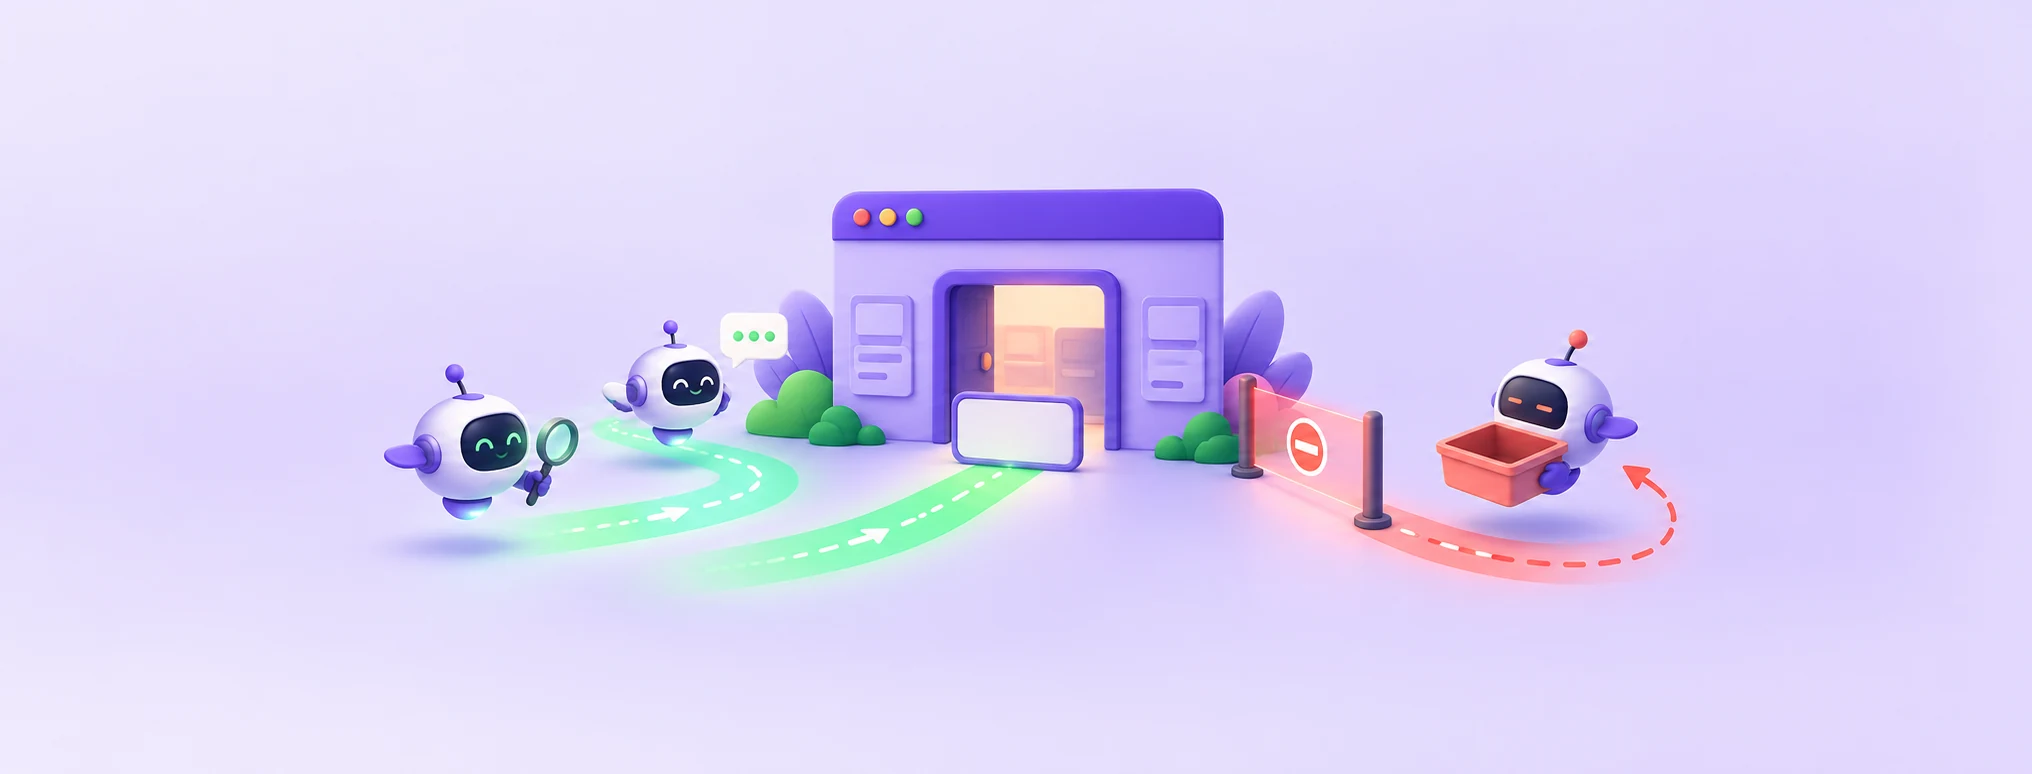
Here is the surprising part. Cloudflare counts Googlebot, Bingbot and Applebot as "mixed-use" crawlers, because one crawler feeds both a search index and AI models. So if you set Training to Block, Cloudflare's own docs say those crawlers get blocked too, even with Search on Allow.
By the end of this guide you will know what each setting does, how to read your current policy, how to set it on purpose, and how to prove that Google can still reach your pages.
What Cloudflare's AI bot policies actually are
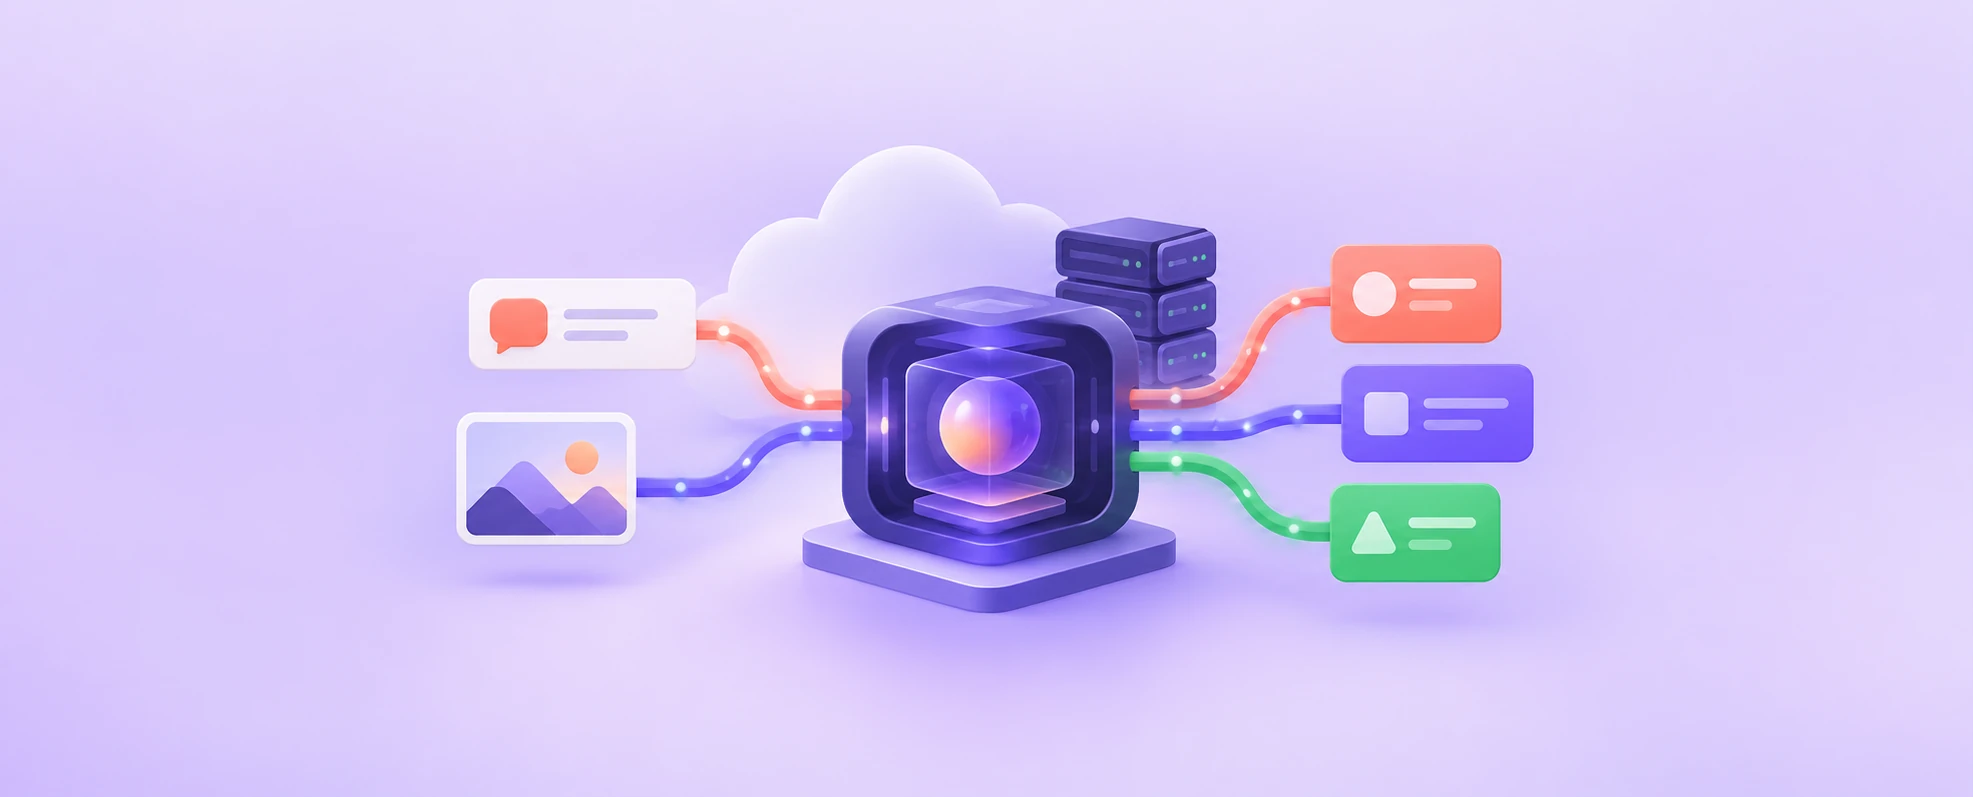
An AI bot policy is a rule at Cloudflare's edge (the Cloudflare servers that sit between visitors and your hosting) that decides what happens when an AI crawler asks for a page. Cloudflare sorts these crawlers by what they do, not by who owns them.
The three categories, in Cloudflare's own words from its 1 July 2026 announcement:
- Search: "any behavior that collects or indexes your content, so it can answer questions about it later."
- Agent: "automated behavior that is acting, usually in real time, on a person's behalf, to get something done right now." Cloudflare gives ChatGPT-User and browser agents like Gemini or Claude driving Chrome as examples.
- Training: "a crawler taking your content to train or fine-tune a model."
Each category gets its own choice. The Cloudflare docs list them as Block (on all pages), Block on pages with ads and Allow (do not block). Training has an extra choice that Cloudflare's docs show as Disallow and its blog calls "Disallow AI Training". The changelog says these controls are open to all customers, including the Free plan.
Think of it like a building with one front desk. Search is the courier who photographs your shop sign for the city directory. Agent is a personal assistant collecting a parcel for one customer right now. Training is someone photocopying your whole catalogue to write their own. The trouble is that some visitors, like Googlebot, are a courier and a photocopier in one uniform.
What changed around 15 September 2026
At the time of writing (27 October 2026), three changes from Cloudflare matter here.
- New domains onboarding to Cloudflare from 15 September 2026 get new defaults. Cloudflare's docs and its July changelog describe Training and Agent as blocked on pages that display ads, with Search allowed. Its 15 September post lists the preset for ad-funded new domains as Training on Disallow AI Training and Agent on Block on pages with ads.
- The legacy Block AI bots setting is marked as deprecating on 15 September 2026, and the 15 September post says Managed robots.txt will be deprecated in favour of Bot Preference Sync.
- For existing domains, the sources differ. The 15 September blog post says existing domains are migrated, that previous Training selections of Block or Block on pages with ads migrate to Disallow AI Training, and that for most customers current settings carry over. The 1 July blog post and the docs page only describe the new defaults for new domains, and say customers could opt out of them before 15 September. The docs page does not say how existing domains are handled.
Heads up: because those pages do not fully agree, do not assume your zone was changed in a particular way. That is the whole point of this guide. Check yours.
What Disallow does that Block does not
Why this matters: the two choices sound alike but treat Google very differently.
Block on Training stops every verified bot classed as Training at the edge. Mixed-use crawlers like Googlebot count as Training, so they are stopped too. That can hurt search visibility.
Disallow works through your robots.txt file. With Bot Preference Sync on, Cloudflare publishes a no-training preference in robots.txt and blocks other training crawlers at the edge. The Cloudflare docs say mixed-use crawlers are excluded from that edge block. The blog adds that accountable mixed-use crawlers from Apple, Google and Microsoft stay allowed for search.
Before you start
You do not need your hosting panel for this, only Cloudflare. Budget about 20 minutes, most of it for checking.
- A Cloudflare login with permission to change security settings for the zone (one domain in Cloudflare is called a zone).
- A terminal with
curl, or any browser, so you can read your liverobots.txt. - Access to Google Search Console for the site, if you have it. It gives the most honest answer about Googlebot.
- A copy of your current
robots.txt, saved before you change anything. - A screenshot of your current AI bot policies, so you can undo a change.
- Risk level: low to medium. A wrong Training setting can reduce search crawling, but it is quick to reverse.
Quick tip: if you are still moving your site onto Cloudflare, finish that first. Our guide on how to map your hosting to your domain covers the DNS side.
Set your Cloudflare AI bot policy on purpose
Cloudflare labels can move between dashboard versions. The steps below follow Cloudflare's docs as opened on 27 October 2026. If a label on your screen differs slightly, look for the same words nearby.
Step 1: Save your current robots.txt
Do this first so you have a clean "before" picture. This command downloads your live robots.txt into a file named with today's date.
curl -s https://example.com/robots.txt -o robots-before-$(date +%F).txtReplace example.com with your domain. You should see a new file in your current folder. Open it and look for a block that starts with # BEGIN Cloudflare Managed content. If you see one, Cloudflare is already adding managed lines to your file.
Step 2: Open the AI bot policies screen
Log in to Cloudflare and pick your domain. Open the Security Settings page at Security > Settings, filter by Bot traffic, then select Configure AI bot policies.
You should now see the three categories, Search, Agent and Training, each with its current choice. Take your screenshot now.
Heads up: if you also see an older Block AI bots option, that is the legacy setting. Cloudflare's docs mark it as deprecating on 15 September 2026, so use the category controls instead.
Step 3: Read your current settings honestly
Before you click anything, compare what you see with this short reading guide.
- Search on Allow and Training on Disallow: AI training crawlers are asked to stay away and most are blocked at the edge, while Googlebot, Bingbot and Applebot keep crawling for search.
- Training on Block or Block on pages with ads: training crawlers are stopped at the edge, and mixed-use crawlers like Googlebot can be stopped too.
- Everything on Allow: nothing is blocked, and Cloudflare serves your
robots.txtunchanged. - Agent on Block on pages with ads: real-time assistant fetches are stopped on pages that display ads.
Made-up example: Priya runs a recipe blog with display ads. Months ago she set Training to Block because she did not want her recipes used for AI training, and she never came back to this screen. After the mixed-use change, her traffic from Google dips over a few weeks. Nothing is broken at her host. Her Training setting is doing exactly what it says, and Googlebot counts as Training. This story is invented to show the pattern.
Step 4: Choose Search
For almost every public website, set Search to Allow (do not block). Search crawlers are the ones that can send visitors back to you.
Block Search only if you truly do not want to appear in AI-powered search answers, and accept the traffic cost.
Step 5: Choose Training
If you want to opt out of AI training but stay in normal search, set Training to Disallow. This is the option Cloudflare's blog calls Disallow AI Training.
If you are happy for your content to be used for training, choose Allow (do not block) instead. That is a fair choice too, especially for documentation or public-interest content.
Avoid Block or Block on pages with ads for Training unless you have accepted that Googlebot, Bingbot and Applebot may be blocked along with it.
Step 6: Turn on Bot Preference Sync
On the same screen, turn on Enable Bot Preference Sync. Without it, Cloudflare does not add your preferences to robots.txt, so crawlers that read the file never learn your choice.
Cloudflare's docs say that with Bot Preference Sync on, setting Training to Disallow adds managed directives and turns on edge blocking for AI training crawlers. Search and Agent also add their own directives when set to Block or Block on pages with ads.
Step 7: Choose Agent and save
Agent traffic is a person's assistant fetching a page right now, for example to answer a question or compare prices. Many shops and support sites want these to work, so Allow (do not block) is a reasonable default.
If agents are draining your ad revenue, Block on pages with ads is the middle ground. Then select Save.
Cloudflare's docs say the managed content appears in your robots.txt within a few seconds, and no cache purge is needed.
Extra steps for Google, Bing and Apple
The Cloudflare setting covers a lot, but each big search company has its own training switch. According to Cloudflare's 15 September 2026 post, here is where each one stands.
Google: Google-Extended
Google uses a separate robots.txt token called Google-Extended to control whether crawled content may be used for training Gemini models. Google's crawler docs say it "does not impact a site's inclusion in Google Search nor is it used as a ranking signal in Google Search."
These lines tell Google not to use any of your pages for Gemini training, while Googlebot keeps crawling for search.
User-agent: Google-Extended
Disallow: /
If your origin server already serves a robots.txt, add these lines there. Cloudflare's docs say it prepends its managed robots.txt before your existing one and combines both into a single response, so your own lines stay.
Apple: Applebot-Extended
Cloudflare's blog says Apple lets you opt out of training with a Disallow rule for Applebot-Extended, and that Apple has stated this does not affect search ranking. These lines do that.
User-agent: Applebot-Extended
Disallow: /
Bing: not yet through robots.txt
Here is the gap. Cloudflare's blog says Microsoft is building support for a robots.txt no-training preference, targeted for early 2027. Until then, Disallow does not pass a no-training preference to Bing through robots.txt.
For Bing today, the same post points to the NOARCHIVE meta tag plus the Block URLs or Content Removal tool in Bing Webmaster Tools. I did not open Microsoft's own pages for this guide, so read Bing's documentation before you rely on these.
How to check it worked
Settings screens show intent. These checks show what crawlers actually get.
Check 1: Read the live robots.txt
This prints the managed section Cloudflare adds, plus the 12 lines that follow it.
curl -s https://example.com/robots.txt | grep -i -A 12 "BEGIN Cloudflare Managed"With Training on Disallow and Bot Preference Sync on, you should see managed lines and a content signal line. Cloudflare's docs show the default form like this.
User-Agent: *
Content-signal: search=yes, ai-train=no, use=reference
Allow: /
A content signal is a machine-readable line that says how your content may be used: search for search indexes, ai-input for real-time AI answers and ai-train for training. If nothing prints, see the troubleshooting section below.
Check 2: Confirm your own lines survived
This shows the end of the file, where your own rules, such as your sitemap line, usually sit.
curl -s https://example.com/robots.txt | tail -n 20You should see your original rules and your Google-Extended lines if you added them. Compare with the file you saved in Step 1.
Check 3: Ask Google directly
Your laptop is not Googlebot, so curl cannot tell you whether Google gets through. Google's own tool can.
In Google Search Console, paste a page address into the inspection search bar at the top, then click Test live URL. You want to see "URL is available to Google". The Crawl allowed? field should say yes. Google notes that a pass does not guarantee the page will appear in results, but a failure here is a clear warning.
Check 4: Look for blocked crawlers in Security Events
Security Events is Cloudflare's log of requests its security features acted on. Go to Analytics, then the Events tab. Select Add filter to narrow the view, for example to the Block action.
Scroll to Sampled logs. Each entry shows the action taken, the user agent and the path, so look for entries with Googlebot or bingbot in the user agent. If you find one, the Events by service section on the same page lists activity per Cloudflare security feature, which helps you see which feature acted. On the Free plan you get sampled logs only, and the default time range is the last 24 hours.
Quick tip: to check whether a crawler name is a real, verified bot, look it up in Cloudflare Radar's directory at https://radar.cloudflare.com/verified-bots.
Troubleshooting
Googlebot shows up as blocked in Security Events
Symptom: blocked events for Googlebot or bingbot, or a sudden fall in pages crawled. Likely cause: Training is set to Block or Block on pages with ads, which also catches mixed-use crawlers. Fix: set Training to Disallow, turn on Bot Preference Sync, save, then rerun the Search Console live test.
No managed section appears in robots.txt
Symptom: the grep in Check 1 prints nothing. Likely cause: Bot Preference Sync is off, or every policy is set to Allow. Cloudflare's docs say that with every policy on allow there is "nothing to prepend", so the file is served unchanged. Fix: turn on Enable Bot Preference Sync and set at least one policy to Block, Block on pages with ads or Disallow. Then reload the file.
Search Console says "Syntax not understood"
Symptom: Search Console flags the Content-signal line in your robots.txt. Likely cause: Google may not recognise content signals and other newer directives. Fix: usually nothing. Cloudflare's docs say it has seen no impact on crawling rates or SEO from these reports. Just make sure the flagged line is the content signal and not one of your own rules.
An AI crawler ignores your robots.txt
Symptom: you set Disallow, but a crawler still fetches pages. Likely cause: following robots.txt is voluntary, and Cloudflare's docs say some operators ignore it. Fix: with Bot Preference Sync on, Disallow already adds edge blocking for AI training crawlers. For a specific crawler that still gets through, Cloudflare points to AI Crawl Control for crawler-specific blocks.
Your own robots.txt rules seem to vanish
Symptom: your sitemap line or custom rules are missing. Likely cause: Cloudflare's docs treat a file as existing when the origin returns an HTTP 200 response, and they do not describe what happens with other statuses, so a missing or erroring origin file is the first thing to rule out. Fix: ask your host to confirm that robots.txt exists at the origin and returns status 200, then reload the file through Cloudflare.
The settings screen does not match this guide
Symptom: you cannot find Configure AI bot policies, or you only see Block AI bots. Likely cause: a different dashboard version, or a role without security permissions. Fix: ask the account owner for access, and look under the security settings with the Bot traffic filter. Labels may differ slightly between versions.
Pro tips and when to ask for help
Write down your choice and the reason, for example "Training: Disallow, 27 October 2026, we do not license content for training". Next time Cloudflare changes defaults, you will know what you meant.
Review this screen whenever you add a new domain to Cloudflare. New domains can get the new defaults, and an ad-funded site may start with Agent blocked on pages with ads.
While you are in the Cloudflare dashboard, it is a good moment to turn on DNSSEC and add the DS record at your registrar. If your goal is more search traffic overall, page speed matters too, and our guide on how to improve website speed is the next stop.
Ask a developer or your SEO person if Search Console still fails the live test after you set Training to Disallow, or if your robots.txt is generated by a plugin or app. Two systems writing one file can surprise you.
The one message worth forwarding
Copy this to whoever manages your Cloudflare account:
"Hi, can you check our Cloudflare AI bot policies? Path: Security > Settings, filter Bot traffic, Configure AI bot policies. We want Search on Allow, Training on Disallow (not Block, because Block can also stop Googlebot and Bingbot), Agent on Allow unless we agree otherwise, and Enable Bot Preference Sync on. After saving, please check https://example.com/robots.txt for the Cloudflare managed section and run a Search Console live test on our home page. Thanks."
If you remember one thing: on Cloudflare, Training set to Block can mean Googlebot blocked, so choose Disallow when you want search traffic without AI training.
Reader questions
Is Cloudflare's AI bot control available on the Free plan?
Yes. Cloudflare's changelog says the Search, Agent and Training controls are available to all customers, including the Free plan, and its docs say managed robots.txt for AI crawlers is available on all plans.
Does blocking Google-Extended hurt my Google rankings?
Google says Google-Extended does not affect a site's inclusion in Google Search and is not used as a ranking signal. It only controls whether crawled content may be used for Gemini training and grounding.
What is the difference between Block and Disallow for Training?
Block stops Training-classed bots at Cloudflare's edge, and that includes mixed-use crawlers like Googlebot. Disallow publishes a no-training preference in robots.txt and blocks other training crawlers, while mixed-use crawlers stay allowed for search.
Does Disallow stop Bing from training on my content?
Not through robots.txt yet. Cloudflare says Microsoft's support for the robots.txt no-training preference is targeted for early 2027, and points to the NOARCHIVE tag and Bing Webmaster Tools for now.
Will Cloudflare overwrite my existing robots.txt?
No. When your origin returns a robots.txt file, Cloudflare's docs say it prepends its managed robots.txt and combines both into a single response. If you have no file, Cloudflare creates one for you.
Do I need to purge the cache after changing AI bot policies?
No. Cloudflare's docs say the managed content appears in robots.txt within a few seconds of saving and no cache purge is required.
Is robots.txt enough to stop every AI crawler?
No. Following robots.txt is voluntary and some crawlers ignore it, so Cloudflare uses edge blocking alongside it and offers AI Crawl Control for crawler-specific blocks.
Was this guide helpful?
Help us make the next update better.
Sources & further reading
- Cloudflare Docs: Block AI bots and AI bot policies
- Cloudflare Docs: robots.txt setting and Bot Preference Sync
- Cloudflare Changelog: AI traffic options for Search, Agent and Training
- Cloudflare Blog: Search, Agent and Training options
- Cloudflare Blog: Accountable mixed-use AI crawlers
- Cloudflare Docs: Verified bots
- Cloudflare Docs: Security Events
- Google: List of Google's common crawlers
- Google Search Console Help: URL Inspection tool
- Help Net Security: Cloudflare AI crawler controls
What changed
Reviewed 28 October 2026 against Cloudflare's AI bot policy, Bot Preference Sync and mixed-use crawler documentation. Added rollback prerequisites and original article media; no live Cloudflare zone was changed by this guide.
Originally published . About our editorial updates.