robots.txt Rules for GPTBot, ClaudeBot and Google-Extended
OpenAI, Anthropic and Google run separate bots for training and search. Here are example robots.txt rules for each, and how to check the file actually works.
On this page
The short answer
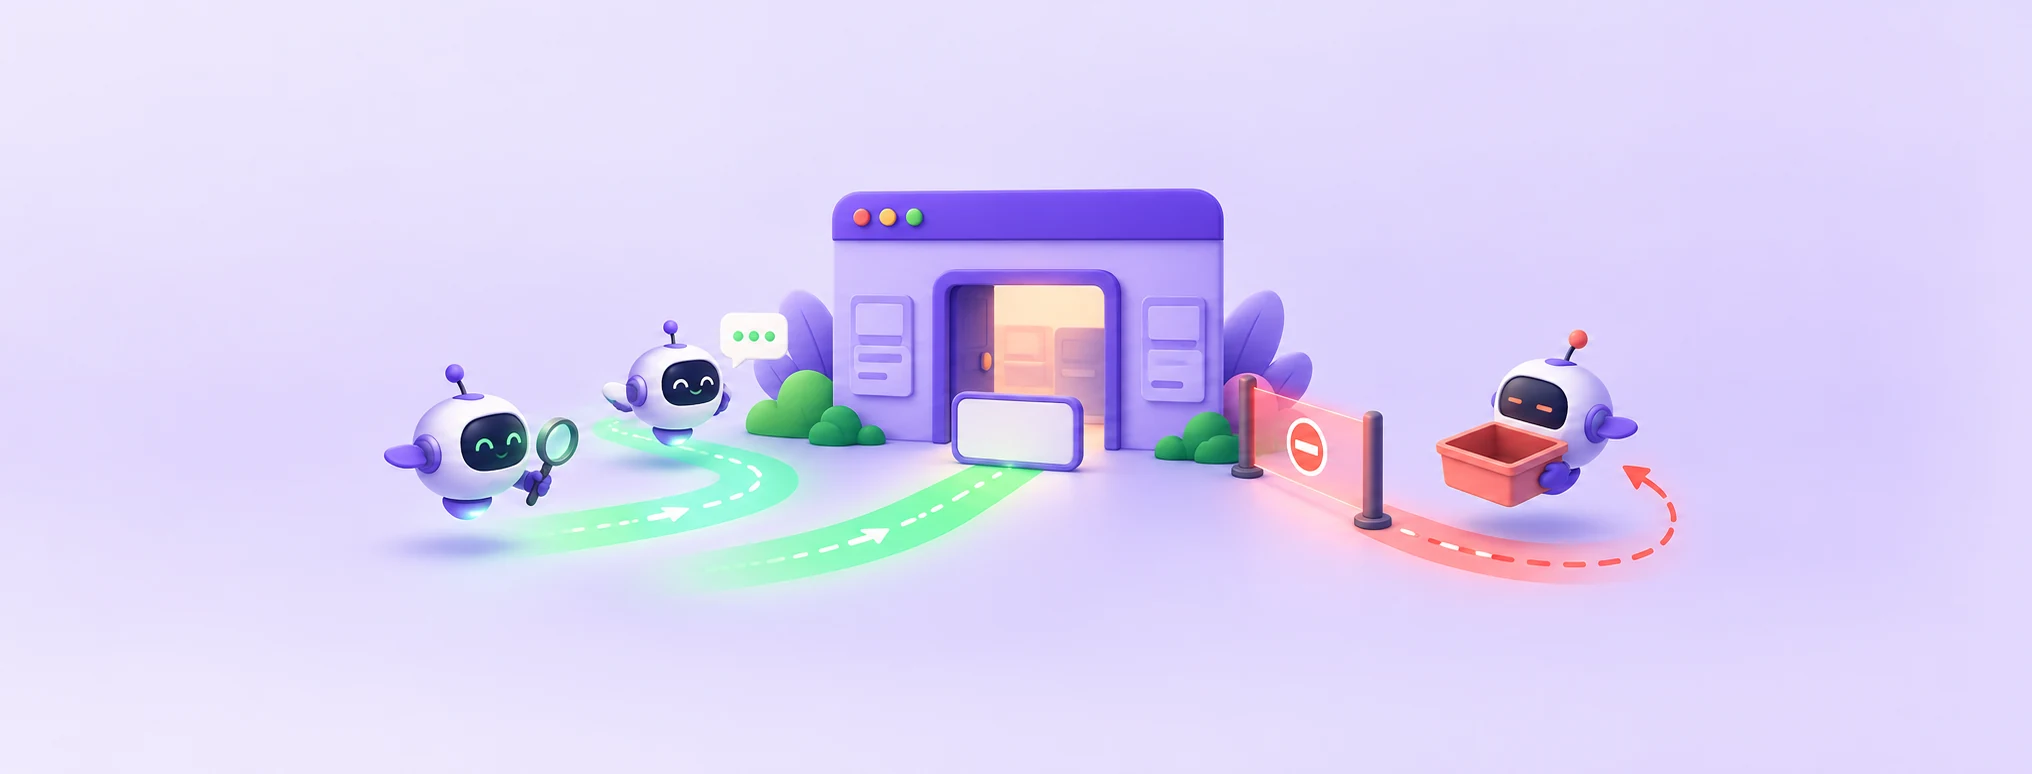
To ask AI companies not to train on your site, add robots.txt groups with Disallow: / for GPTBot (OpenAI), ClaudeBot (Anthropic) and Google-Extended (Google). Search and user-request bots such as OAI-SearchBot, Claude-SearchBot and ChatGPT-User are separate names, so blocking training does not remove you from AI search. Google-Extended does not affect Google Search inclusion or ranking. robots.txt is a request to compliant bots, not access control, so private content still needs a password or firewall.
You can ask AI companies not to train on your site with a few lines in robots.txt: a User-agent: GPTBot group for OpenAI, a User-agent: ClaudeBot group for Anthropic and a User-agent: Google-Extended group for Google, each with Disallow: /. The part most people miss is that each vendor now runs separate bots for training, for search and for fetching a page when a person asks, so one line no longer covers everything. By the end of this guide you will know which name does what, have example rules you can paste, and know how to check that the file actually works.
Here is a surprising fact: Google-Extended never shows up in your access logs. Google says it "doesn't have a separate HTTP request user agent string". Crawling is done with Google's existing user agents, and the Google-Extended token is only read from robots.txt as a control switch. So if you were waiting to "see it" before deciding, you will wait forever.
What robots.txt actually is
robots.txt is a plain text file at the root of your site, for example https://example.com/robots.txt. It tells crawlers (programs that visit pages automatically) which paths you would like them to skip. The rules are defined in RFC 9309, the Robots Exclusion Protocol, published by the IETF.
Think of it as a sign on your front gate that says "No flyers, please". Polite delivery people read it and walk past. Someone who ignores signs can still open the gate. RFC 9309 says the same thing in standards language: the rules "are not a form of access authorization", and the protocol "is not a substitute for valid content security measures".
Why this matters: robots.txt is a request to well-behaved bots. If you have private pages, client files or a staging site, you need real access control, such as HTTP authentication (a username and password prompt from the web server), a login, or a firewall rule. Do not rely on robots.txt to hide anything.
The bots you are actually choosing between
Each vendor below publishes its own crawler names. I checked every description against the official pages on 14 October 2026.
OpenAI (from its "Overview of OpenAI Crawlers" page):
GPTBot: crawls content that "may be used in training our generative AI foundation models". Disallowing it "indicates a site's content should not be used in training".OAI-SearchBot: used for search. Sites opted out of it "will not be shown in ChatGPT search answers", though they "can still appear as navigational links".ChatGPT-User: visits a page when a user asks ChatGPT or a Custom GPT a question. OpenAI says it "is not used for crawling the web in an automatic fashion" and that "because these actions are initiated by a user, robots.txt rules may not apply."OAI-AdsBot: checks the safety of pages submitted as ads on ChatGPT, and only visits those pages. OpenAI says its data is not used to train foundation models.
OpenAI also says "each setting is independent of the others", and that search changes can take about 24 hours after you update robots.txt.
Anthropic (from its Help Center article on crawling):
ClaudeBot: blocking it signals that your site's future material should be excluded from Anthropic's AI model training datasets.Claude-User: fetches pages when people ask Claude questions. Blocking it stops Anthropic retrieving your content in response to a user query, which may reduce your visibility in user-directed web search.Claude-SearchBot: crawls to improve search result quality. Blocking it stops your content being indexed for search, which may reduce visibility in search results.
Anthropic says its bots honor robots.txt directives and "will not attempt to bypass CAPTCHAs".
Google (from its "Google's common crawlers" page, last updated 14 July 2026):
Google-Extended: a robots.txt product token that controls whether content Google crawls may be used for training future Gemini models, and for grounding (giving Search index content to the model at prompt time) in Gemini Apps and Grounding with Google Search on Vertex AI.Googlebot: controls crawling for Google Search, including Discover, Google Images, Google Video and Google News.
Google is explicit that Google-Extended "does not impact a site's inclusion in Google Search nor is it used as a ranking signal". Blocking Google-Extended will not remove you from Google Search. Blocking Googlebot would, so be careful which one you type.
How crawlers read your groups
A few RFC 9309 rules decide whether your file does what you think:
- A group starts with one or more
User-agentlines, followed byAllowandDisallowrules. It ends at the nextUser-agentline. - Bot names are matched case-insensitively, so
gptbotandGPTBotare the same. Paths are matched case-sensitively, so/Private/and/private/are different. - If several rules match a URL, the longest (most specific) one wins. If an
Allowand aDisalloware equally specific,Allowwins. - A bot that finds a group with its own name follows only that group. It uses the
User-agent: *group only when no group names it. - If two groups name the same bot, the crawler must combine their rules into one group.
*matches any run of characters and$marks the end of a URL. A#starts a comment.
Heads up: that fourth rule catches a lot of people. If your User-agent: * group blocks /wp-admin/ and you add a separate User-agent: GPTBot group, GPTBot no longer reads the * group at all. Copy any shared rules into the named group too.
Before you start
Give yourself about 20 minutes. The risk is low if you keep a backup, but a typo in the wrong group (such as Googlebot instead of Google-Extended) can hurt your search traffic.
- Access to your site files: your hosting control panel's file manager, SFTP or SSH.
- Your document root, the folder your domain serves files from. On cPanel hosting the cPanel docs call it the web root, usually
public_htmlorwww. - A plain text editor. Avoid word processors, which can add hidden formatting.
- A terminal with
curl, or just a web browser. - A decision, written down in one sentence, such as "No AI training, but yes to AI search".
- Optional: a Google Search Console property for your domain, so you can use the robots.txt report.
If you are new to how files reach the web, our guide on what web hosting is explains the document root and how a request gets to your server.
Step-by-step: write and publish your AI crawler rules
Step 1: Back up your current file
Your site may already have a robots.txt, written by you, a plugin or your CMS. Save a copy before you touch anything.
This command downloads your live file into a local backup:
curl -sS -o robots-backup.txt https://example.com/robots.txtOpen robots-backup.txt. If it contains your existing rules, keep it safe. If it contains an HTML error page, you do not have a working file yet, and you will create one in Step 3.
Quick tip: on WordPress, check whether a real robots.txt file exists in the document root. WordPress has a do_robots() function that outputs a default robots.txt, and some SEO plugins edit that output. If you see content at the URL but no file on disk, it is being generated, and you should change it where it is generated or replace it with a real file after checking with your host.
Step 2: Decide your policy
Before writing rules, pick one of these common positions:
- No training, yes to AI search and user fetches. You block
GPTBot,ClaudeBotandGoogle-Extendedand leave the search and user bots alone. - No AI use at all. You also block
OAI-SearchBot,Claude-SearchBot,Claude-UserandChatGPT-User, and accept that you will drop out of those AI search answers. - Training allowed, but not for one section, such as paid members' articles.
- Everything allowed, but slower, for a small server that struggles with crawl traffic.
Made-up example: Amira runs a recipe blog on shared hosting. She is happy for ChatGPT search and Claude to link to her recipes, because those links bring readers. She does not want her writing used to train models. That is the first position, and the first example in Step 3 is written for exactly her case.
Step 3: Write the file
Pick the example that matches your policy. These are examples I wrote in RFC 9309 syntax, not files published by the vendors. Replace the folder names with your own.
This example opts out of AI training from all three vendors while leaving search crawlers and everything else allowed:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
The search bots (OAI-SearchBot, Claude-SearchBot) and Googlebot are not named, so they follow the * group and can crawl everything except /wp-admin/. Remove the two wp-admin lines if your site is not WordPress.
Heads up: blocking Google-Extended also covers grounding in Gemini Apps and Grounding with Google Search on Vertex AI, according to Google. If you want Gemini to be able to ground answers in your pages, that is a trade-off to think about.
This example asks every AI bot listed by these vendors to stay away, including search and user-initiated fetchers:
User-agent: GPTBot
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: ClaudeBot
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: Google-Extended
Disallow: /

User-agent: *
Allow: /
Several User-agent lines in a row form one group, which keeps the file short. Remember the limits: OpenAI says robots.txt rules may not apply to ChatGPT-User, and your site will not appear in ChatGPT search answers once OAI-SearchBot is blocked.
This example allows training on public posts but asks training bots to skip a members area and a downloads folder:
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
Disallow: /members/
Disallow: /downloads/

User-agent: *
Allow: /
If /members/ is truly private, it needs a login as well. The Disallow only stops compliant crawlers from asking for it.
This example slows down ClaudeBot using Crawl-delay, which Anthropic describes as a "non-standard" extension it supports:
User-agent: ClaudeBot
Crawl-delay: 1

User-agent: *
Allow: /
Crawl-delay is not part of RFC 9309, so do not assume other crawlers honor it.
Quick tip: if you mix patterns, remember that the longest match wins. With Disallow: /blog/ and Allow: /blog/public/ in the same group, URLs under /blog/public/ are allowed and the rest of /blog/ is not.
Step 4: Upload it to the document root
The file must be named robots.txt, all lowercase, and sit at the top level of the host. RFC 9309 asks for UTF-8 text served as text/plain.
In cPanel, open File Manager and go to public_html (or the document root shown for your domain). If a robots.txt already exists, select it and choose Edit. If not, click + File, type robots.txt in the New File Name: box, and click Create New File, then edit it. Paste your rules and save.
If you use SFTP or SSH, upload the file into the document root. On a server with shell access, this command shows the start of the file you just placed so you can confirm it is the right one:
head -n 20 /path/to/your/document-root/robots.txtYou should see your new rules, starting with the first User-agent line.
Heads up: subdomains are separate hosts. blog.example.com needs its own https://blog.example.com/robots.txt. Anthropic says to add the rule for each subdomain you want to opt out.
Step 5: Give it time
Crawlers do not reread the file on every request. RFC 9309 says a crawler should not use a cached copy for more than 24 hours, unless the file cannot be reached. OpenAI separately says search changes can take about 24 hours. Plan to check results the next day, not the next minute.
How to check it worked
Check the file in a browser
Open https://example.com/robots.txt in a private browser window. You should see your rules as plain text, with no HTML, no login prompt and no "page not found" page.
Check the status code and content type
This command asks the server for the headers only:
curl -sI https://example.com/robots.txtYou want to see a 200 status on the first line, for example HTTP/2 200, and a content-type header that starts with text/plain. A redirect (301 or 302) is not fatal, since RFC 9309 says crawlers should follow at least five redirects, but a direct 200 is cleaner.
Check what a specific bot would get
Some servers or firewalls treat bots differently. This command requests the file while identifying as GPTBot by its product token, so you can spot a firewall rule that blocks it:
curl -sS -A "GPTBot" https://example.com/robots.txtYou should get the same text as in your browser. If you get a 403 or a challenge page, something in front of your site is blocking the bot before it can read your rules. Anthropic warns that IP-based blocking "impedes our ability to read your robots.txt file", so make sure the file itself stays reachable.
Check with Google Search Console
If you have a domain-level property in Google Search Console, open the robots.txt report from Google's help page on the report. Google says the report "shows which robots.txt files Google found for the top 20 hosts on your site", with the fetch status, the last check time and any parsing issues. After a critical change, you can use the more settings icon next to a file and click Request a recrawl.
This report only shows Google's view, not OpenAI's or Anthropic's.
Troubleshooting
Your rules show up in the browser, but the bots ignore them
Symptom: you still see GPTBot or ClaudeBot requests in your access logs after a day or more. Cause: often the file sits in the wrong folder, the wrong host (www versus non-www), or a subdomain without its own file. Fix: open the exact host the bot is visiting plus /robots.txt and confirm your rules appear there. Also confirm the requests come from the vendor: Anthropic publishes its IP ranges at https://claude.com/crawling/bots.json, and OpenAI publishes https://openai.com/gptbot.json, https://openai.com/searchbot.json and https://openai.com/chatgpt-user.json. A request that only claims to be GPTBot in its user agent string may be someone else.
The robots.txt URL returns a 404
Symptom: the browser shows "Not Found" and curl -sI shows 404. Cause: there is no file, or it is named Robots.txt or robots.txt.txt. Fix: rename it to exactly robots.txt in the document root. Why this matters: under RFC 9309, a 4xx response means crawlers may access any resource on your site, so a missing file means no rules at all.
The robots.txt URL returns a 500 or 503
Symptom: curl -sI shows a 5xx status. Cause: a server error, a broken plugin, or an overloaded server. Effect: RFC 9309 says crawlers must assume a complete disallow when the file is unreachable, which can quietly stop Googlebot crawling your whole site. Fix: check your error logs, disable the plugin that generates the file, or upload a static file. Ask your host if the error continues.
Your blog vanished from Google after the edit
Symptom: pages drop out of Google Search. Cause: you probably wrote User-agent: Googlebot with Disallow: /, or put Disallow: / in the * group. Fix: restore your backup from Step 1, then add only the Google-Extended group. Google states that Google-Extended does not affect inclusion in Google Search. Use the robots.txt report to request a recrawl.
The bot ignores your general rules after you added its own group
Symptom: GPTBot now crawls /wp-admin/ even though your * group blocks it. Cause: once a bot has its own group, it ignores the * group. Fix: copy the shared Disallow lines into the bot's named group.
A WAF or bot protection blocks the bot from reading the file
Symptom: curl -sS -A "ClaudeBot" https://example.com/robots.txt returns a 403 or a challenge page. Cause: a firewall or bot management rule matches the bot name. Fix: add an exception for the /robots.txt path so bots can read your instructions, even if you block them elsewhere. Our post on a Cloudflare WAF rule for an Atlassian CVE shows how firewall rules work in practice.
Changes do not appear for a day
Symptom: you edited the file an hour ago and nothing changed. Cause: caching, as covered in Step 5. Fix: wait a day, and avoid repeated edits in that window so you know which version a bot saw.
Pro tips and security notes
Consider a comment line at the top with the date and your policy (RFC 9309 comments start with #). The next person to edit the file (possibly you, in a year) will thank you.
Do not list secret paths in robots.txt. The file is public, so a Disallow: /secret-admin-panel/ line tells everyone where to look. Protect such paths with a password and leave them out of the file.
If you need to stop bots for real, the controls live outside robots.txt: HTTP authentication, a login, or firewall rules at your host or CDN. Be aware that Anthropic says IP blocking "may not work correctly or persistently guarantee an opt-out", and recommends robots.txt for opting out. For a broader look at how AI agents fetch pages, see our post on Cloudflare's web fetch for AI agents.
Ask your host or a developer for help if robots.txt is generated by your platform and you cannot find where, if the URL returns 5xx errors, or if a security layer in front of your site blocks requests you cannot trace.
The one message worth forwarding
Copy this to whoever manages your site:
"Hi, could you update our robots.txt at the site root? Please add groups with Disallow: / for GPTBot, ClaudeBot and Google-Extended, so we opt out of AI training. Please do not block Googlebot, OAI-SearchBot or Claude-SearchBot, because we still want to appear in Google Search and AI search. Copy any shared rules from the User-agent: * group into the new groups. Back up the current file first, then confirm that curl -sI https://example.com/robots.txt returns 200 with text/plain. If anything on the site is private, it needs a password or firewall rule, not just robots.txt. Thanks!"
The takeaway: name each bot by its purpose, keep Googlebot out of your block list unless you mean it, and use real access control for anything that must stay private.
Reader questions
Will blocking Google-Extended hurt my Google rankings?
No. Google states that Google-Extended does not impact a site's inclusion in Google Search and is not used as a ranking signal. Search crawling is controlled by the Googlebot token, so leave that one alone.
Does blocking GPTBot remove my site from ChatGPT search?
No. OpenAI treats each bot setting as independent, and ChatGPT search uses OAI-SearchBot. Only sites that opt out of OAI-SearchBot are left out of ChatGPT search answers, though they can still appear as navigational links.
Why do I not see Google-Extended in my server logs?
Google-Extended has no separate HTTP user agent string. Google crawls with its existing user agents and only reads the Google-Extended token from robots.txt as a control.
Does blocking ClaudeBot remove content Anthropic already collected?
Anthropic says blocking ClaudeBot signals that your site's future materials should be excluded from its training datasets. Its article does not describe removing content collected earlier.
Can I use robots.txt to keep a private folder secret?
No. RFC 9309 says the rules are not a form of access authorization, and the file is public, so listing a path can draw attention to it. Protect private folders with a login, HTTP authentication or a firewall rule.
Do I need a separate robots.txt for each subdomain?
Yes. Each host reads its own file at its own /robots.txt, and Anthropic says to add its rule for each subdomain you want to opt out.
How long until crawlers see my new rules?
RFC 9309 says crawlers should not use a cached copy for more than 24 hours, and OpenAI says its search systems can take about 24 hours to adjust. Check again the next day.
Sources & further reading
- OpenAI: Overview of OpenAI Crawlers
- Anthropic Help Center: Does Anthropic crawl data from the web, and how can site owners block the crawler?
- Google Search Central: Google's common crawlers
- RFC 9309: Robots Exclusion Protocol
- Search Console Help: robots.txt report
- cPanel Docs: File Manager
- WordPress Developer Reference: do_robots()
Originally published . About our editorial updates.