Block AI Training, Keep Search: robots.txt Rules That Work
Opt out of AI model training in robots.txt while Googlebot, Bingbot, Applebot and OAI-SearchBot keep indexing your site, then test every rule with curl.
The short answer
Disallow Google-Extended, Applebot-Extended and GPTBot while keeping Googlebot, Bingbot, Applebot and OAI-SearchBot open. Search eligibility stays intact, but blocking Google-Extended also opts crawled content out of grounding uses in Gemini Apps and Gemini on Vertex AI. Robots.txt is a preference, not an access-control lock, so verify search crawlers still receive 200 responses and use CDN enforcement for non-compliant bots.

Reading options
On this page
- What robots.txt actually is
- The names that matter: training crawlers versus search crawlers
- Before you start
- Step by step: write the rules
- Checking for syntax mistakes
- Cloudflare: when to use a setting instead of the file
- How to check it worked
- Troubleshooting
- Pro tips and when to call for help
- The one message worth forwarding
- Reader questions
- Sources & further reading
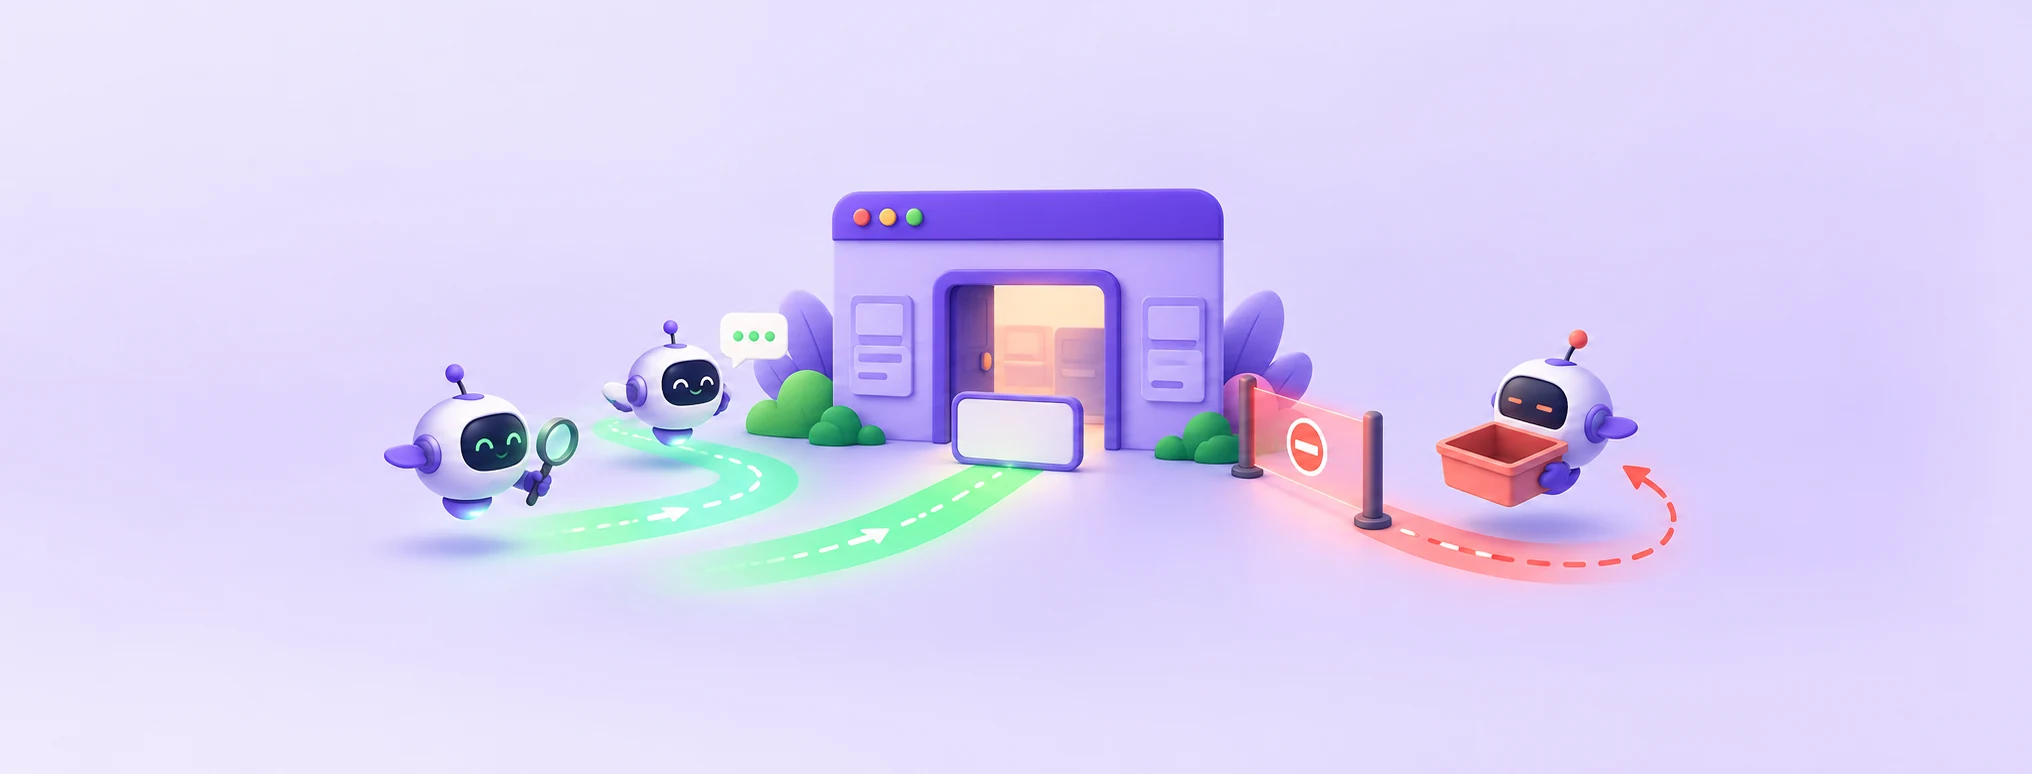
You can tell the big AI companies not to train on your site and still stay fully visible in search, and you do it with a few lines in one small text file. The trick is that training and search now use different names in robots.txt, so you block the training names and leave the search names alone. Get the names mixed up and you can quietly fall out of Google, which is the one mistake this guide is built to prevent.
Here is the fact that surprises most people: Google's training opt-out, Google-Extended, never visits your site at all. Google says it "doesn't have a separate HTTP request user agent string" and that crawling "is done with existing Google user agent strings." It is a label for what Google may do with pages Googlebot already fetched, and Apple's Applebot-Extended works the same way.\n\nThere is an AEO/GEO tradeoff to make consciously: blocking Google-Extended leaves Google Search inclusion and ranking unchanged, but Google also uses this token to control whether crawled content may support grounding in Gemini Apps and Gemini on Vertex AI. Blocking it can therefore reduce eligibility to appear as a grounded source in those AI answers. Blocking GPTBot remains independent from allowing OAI-SearchBot for ChatGPT search.
By the end of this guide you will have a backed up, tested robots.txt that says no to AI training, yes to search, and you will know how to prove that Googlebot still gets a normal page.
What robots.txt actually is
A robots.txt file is a plain text note at the top of your site that tells automated visitors (crawlers, also called bots) which parts they may fetch. The rules come from a standard, RFC 9309, which says the file must sit at /robots.txt on each host, be UTF-8 text, and be served as text/plain.
Think of it as a sign on a farm gate: "pickers welcome, photographers please stay out." Honest visitors respect it. It does not lock the gate.
That last point is official. RFC 9309 says the rules "are not a form of access authorization." Cloudflare's own docs say the same thing more bluntly: compliance is voluntary and some crawler operators may disregard your directives.
Why this matters: robots.txt is a request. It works with the large companies covered here. For a bot that ignores it, you need a firewall or CDN rule.
Note that robots.txt is not llms.txt. If you wonder whether you need that one too, read do you need llms.txt.
The names that matter: training crawlers versus search crawlers
Each crawler announces a name called a user agent token, the short word you put after User-agent: in the file. Matching is case-insensitive under RFC 9309, so gptbot and GPTBot are treated the same, but we write them the way the vendors do.
These are the training tokens, the ones you will disallow:
Google-Extended: Google says it does not affect inclusion or ranking in Google Search. It also controls whether crawled content may be used for grounding in Gemini Apps and Gemini on Vertex AI, so disallowing it carries that separate answer-engine visibility tradeoff.Applebot-Extended: Apple says it "does not crawl webpages" and that pages which disallow it "can still be included in search results."GPTBot: OpenAI says disallowing it "indicates a site's content should not be used in training generative AI foundation models."
These are the search tokens, the ones you must leave open:
Googlebot: Google Search.Bingbot: Bing's standard crawler, which Microsoft says "handles most of our crawling needs each day."Applebot: Apple's search crawler. Apple notes that if your file does not mentionApplebotbut does mentionGooglebot, Applebot will follow the Googlebot instructions.OAI-SearchBot: OpenAI's crawler for ChatGPT search. OpenAI says sites that opt out "will not be shown in ChatGPT search answers."
OpenAI says "each setting is independent of the others", so you can disallow GPTBot and still allow OAI-SearchBot.
Heads up: ChatGPT-User fetches a page when a person asks ChatGPT to, and OpenAI says "robots.txt rules may not apply" to it. Do not expect your file to control it.
Bing is the odd one out. At the time of writing (11 November 2026), the latest report we found is from Search Engine Journal, which reported on 15 September 2026 that Bing does not yet read a no-training preference from robots.txt. Keep Bingbot allowed and check Bing Webmaster Tools help for its current AI controls.
Before you start
Give yourself about 20 minutes. The risk is low with a backup, and high if you guess, because one wrong line can turn Googlebot away.
- Access to your site files: cPanel File Manager, SFTP, or SSH. The file lives in your web root, often
public_html. - A terminal with
curlinstalled, on your computer or on the server over SSH. - A plain text editor that saves UTF-8 (VS Code, Notepad++, nano). Not a word processor.
- Google Search Console access, for the robots.txt report.
- Your Cloudflare login, if you use Cloudflare, because it can add lines to the file.
- A backup of the current file. Step 2 covers this.
Step by step: write the rules
Step 1: Look at what you have now
First, see the live file the way a crawler sees it. This command prints the response headers, so you learn the status code and the content type.
curl -I https://example.com/robots.txtYou want to see HTTP/2 200 (or HTTP/1.1 200 OK) and a content-type line that starts with text/plain. Then print the file itself with this command.
curl https://example.com/robots.txtFor a browser check, Google suggests opening a private browsing window and going to https://example.com/robots.txt. A private window skips your logged-in cookies, so you see what the public sees.
Quick tip: robots.txt is per host, so https://example.com/robots.txt and https://www.example.com/robots.txt are separate files to a crawler. Check both. If one host redirects to the other, make sure the file you end up on is the one you expect. Our guide on www vs non-www redirects explains how to set that redirect up cleanly.
Step 2: Back up the current file
Next, save a copy on your own computer. This is the download command Google gives in its own guide to updating robots.txt.
curl https://example.com/robots.txt -o robots.txtIf you have SSH access, also make a copy on the server next to the original. The -p flag keeps the file's mode, owner and timestamps.
cd ~/public_html
cp -p robots.txt robots.txt.bak
ls -l robots.txt robots.txt.bak
You should see two files with the same size. Without SSH, use your file manager to make the same copy.
Heads up: a .bak file in your web root is public at https://example.com/robots.txt.bak. It holds nothing secret, but delete it once you are happy with the new file, or keep the backup in your home folder instead.
If you get a 404, there is nothing to back up, and you will create the file.
Step 3: Write the new file
Now the main part. Here is a made-up example: a small bakery blog at example.com wants to appear in Google, Bing, Apple and ChatGPT search, keeps a /drafts/ folder out of all crawlers, and does not want its recipes used for AI training.
This file does exactly that. Lines that start with # are comments and crawlers ignore them.
# Search crawlers: welcome
User-agent: Googlebot
User-agent: Bingbot
User-agent: Applebot
User-agent: OAI-SearchBot
Disallow: /drafts/

# AI training: please do not use this site
User-agent: Google-Extended
User-agent: Applebot-Extended
User-agent: GPTBot
Disallow: /

# Every other crawler
User-agent: *
Disallow: /drafts/
A group is one or more User-agent: lines followed by rules, as RFC 9309 defines it. So the first group covers four search crawlers at once, and the second covers three training names.
The search group repeats Disallow: /drafts/ on purpose.
Why this matters: Google's crawlers pick the single most specific group that names them, and Google says "only one group is valid for a particular crawler." Once Googlebot finds its own group, it ignores the User-agent: * group completely. Any rule you want Googlebot to follow must sit inside its own group.
If you have no folders to hide from search, give the search group a single rule that allows the whole site.
User-agent: Googlebot
User-agent: Bingbot
User-agent: Applebot
User-agent: OAI-SearchBot
Allow: /
Want to opt out of training for only part of the site? Apple's own example does that for one folder.
User-agent: Applebot-Extended
Disallow: /private/
Paths are case-sensitive for Google, so /Private/ and /private/ differ.
Keep any Sitemap: line your current file already has. Copy it into the new file unchanged.
Step 4: Upload the file
Save the file as UTF-8 plain text named robots.txt, all lowercase, and upload it to the root of the site. Google's rule is strict: it "cannot be placed in a subdirectory." A file at https://example.com/blog/robots.txt is ignored.
Upload it to public_html (or the domain's document root) with your file manager or SFTP. Over SSH, these commands open the live file in the nano editor so you can edit it in place.
cd ~/public_html
nano robots.txt
Paste the new rules, then save and exit the editor. Whichever way you upload, the live URL is what counts, so you will check it with curl in a moment.
Checking for syntax mistakes
A wrong file does not throw an error at you. Crawlers just use the lines they can understand and skip the rest. RFC 9309 says crawlers "MUST use the parseable rules" and "SHOULD ignore 'disallow' and 'allow' rules that are not in any group."
So a stray Disallow above the first User-agent line does nothing, and you think you are protected when you are not. This command lists every rule line with its line number, so you can read the structure top to bottom.
grep -n -i -E '^(user-agent|allow|disallow):' robots.txtRead the output and check these points:
- The very first match is a
User-agent:line, neverAlloworDisallow. - Every group has at least one rule after its
User-agent:lines. - The training group says
Disallow: /. - No search token (
Googlebot,Bingbot,Applebot,OAI-SearchBot) appears in a group withDisallow: /. - Each line uses a colon, not a space or equals sign.
This short awk script catches the most dangerous mistake of all: a group that disallows the whole site. It prints the names in every group that has Disallow: /.
awk '{l=tolower($0)} l ~ /^user-agent:/ {if (!g) ua=""; ua=ua " " $2; g=1; next} l ~ /^(allow|disallow):/ {g=0; if (l ~ /^disallow:[ \t\r]*\/[ \t\r]*$/) print "Disallow: / applies to:" ua}' robots.txtFor the file in Step 3 you should see one line: Disallow: / applies to: Google-Extended Applebot-Extended GPTBot. If Googlebot, Bingbot, Applebot, OAI-SearchBot or * shows up in that output, stop and fix it before you go on.
Quick tip: check the encoding too. This command should report plain ASCII or UTF-8 text.
file robots.txtCloudflare: when to use a setting instead of the file
If your domain runs through Cloudflare, you have a second way to say no to training, and it can do something the file cannot: block at the edge.
Cloudflare's docs (last updated 2 November 2026) describe the path. In the Cloudflare dashboard, go to Security > Settings, filter by Bot traffic, then select AI Crawler and Agent access policies. There are separate policies for Search, Agent and Training.
For training, the docs list these steps:
- Go to Security > Settings.
- Filter by Bot traffic.
- Select AI Crawler and Agent access policies.
- For Training, select Disallow.
- Turn on Enable Bot Preference Sync.
- Select Save.
According to Cloudflare, with Bot Preference Sync on, setting Training to Disallow adds managed directives to your robots.txt and also blocks AI training crawlers at Cloudflare's edge. The docs add that mixed-use crawlers, the ones used for both search and training, are excluded from that edge block. Cloudflare says the managed content appears within a few seconds and needs no cache purge.
Cloudflare also merges with your own file. It prepends its lines, starting with # BEGIN Cloudflare Managed content, above whatever your origin server sends. If you have no file, it creates one for you.
Heads up: leave Search on allow. Search Engine Journal reported on 15 September 2026 that choosing Block now stops Googlebot, Applebot and Bingbot as well, including for search. The same report says the older Block AI Bots and Managed robots.txt features are being deprecated and existing Block selections for training move to the new disallow option. The Cloudflare page we checked today only says the feature "was previously called Configure AI bot policies", so treat the deprecation details as reported, not final.
So which should you use? Edit the file yourself when you want exact control over every line, or you are not on Cloudflare. Use the Cloudflare setting when you want enforcement on top of the request, or you manage many domains. If you already run Cloudflare for things like Turnstile spam protection, the setting is right there.
If you use both, you may end up with two training groups. RFC 9309 says groups matching the same crawler "MUST be combined into one group", so it still works, but the file gets harder to read.
How to check it worked
Check the file is live and served correctly
This prints only the status code and content type.
curl -s -o /dev/null -w "%{http_code} %{content_type}\n" https://example.com/robots.txtYou want 200 text/plain (sometimes with ;charset=utf-8 after it). Then print the file and confirm your new groups are there.
curl https://example.com/robots.txtCheck Googlebot still gets 200 for a real page
Your robots.txt is the same for every visitor, but your firewall may not be. This sends Google's published Googlebot Smartphone user agent string and prints the status.
curl -s -o /dev/null -w "%{http_code}\n" -A "Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Build/MMB29P) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/W.X.Y.Z Mobile Safari/537.36 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)" https://example.com/You want 200.
Now the same test with OpenAI's published GPTBot user agent string.
curl -s -o /dev/null -w "%{http_code}\n" -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" https://example.com/With only robots.txt in place, this is also 200, because the file asks and does not block. With Cloudflare edge blocking on, you may see a block here. Both are fine. A block on the Googlebot test never is.
Why this matters: Google says its crawlers identify themselves by user agent, source IP address and reverse DNS hostname. A firewall that checks the IP may treat your fake Googlebot from your laptop differently from the real one. So a 200 from curl is a good sign, and the Search Console report below is the real proof.
Check Google's own view in Search Console
Search Console has a robots.txt report, which Google lists under the property settings. It shows each robots.txt Google found, the fetch status such as "Fetched", when Google last checked it, and any parsing issues.
Google says it refreshes its cached copy about every 24 hours. To speed that up after an edit, click the more settings icon next to the file in the report and choose Request a recrawl. The report works for Domain properties and for URL-prefix properties without a path, such as https://example.com/.
Troubleshooting
curl with the Googlebot user agent returns 403 or a challenge page
Symptom: the Googlebot test prints 403 or 503 instead of 200. Likely cause: a security plugin, ModSecurity rule or CDN bot setting blocks that user agent, or the Cloudflare Search policy is set to Block. Fix: set Search back to allow in AI Crawler and Agent access policies, review any bot rules in your firewall, and run the test again until it prints 200.
robots.txt returns 500 or 503
Symptom: curl -I https://example.com/robots.txt shows a 5xx status. This one is serious. RFC 9309 says that when the file is unreachable, the crawler "MUST assume complete disallow", and Google says it stops crawling the site for the first 12 hours while it retries. Fix: check the server error log, make sure the file exists and the web server can read it, and confirm no rewrite rule sends /robots.txt to a broken script.
robots.txt shows content-type text/html
Symptom: the content type is text/html, and the body looks like your site's 404 page or theme. Likely cause: the file is not at the web root, so your app answers the URL instead. Fix: move robots.txt to the document root of that exact host, then rerun the content type check.
Googlebot crawls a folder you blocked for everyone
Symptom: your access log shows Googlebot fetching /drafts/ pages even though your User-agent: * group disallows them. Likely cause: you added a User-agent: Googlebot group, and Googlebot now follows only that group. Fix: copy the folder rules into the search group, as in Step 3.
Lines you never wrote appear at the top
Symptom: your live file starts with a long comment block and # BEGIN Cloudflare Managed content. Likely cause: Cloudflare Bot Preference Sync is on. Fix: nothing is broken. Keep it and remove your duplicate training lines, or turn the sync off to manage every line yourself.
GPTBot or another AI bot still shows up in your logs
Symptom: your access log shows AI crawler hits after the change. Likely cause: caches. OpenAI says it "can take ~24 hours" for its systems to adjust after a robots.txt update, and RFC 9309 lets crawlers keep a cached copy for up to 24 hours. Also, ChatGPT-User visits come from people asking ChatGPT about a page and may not follow the file. Fix: wait a day, then check again. If a bot keeps ignoring the file, block it at the firewall or CDN.
Pro tips and when to call for help
Keep the file short. Google ignores anything past 500 KiB, and long copy-pasted bot lists are where mistakes hide.
Watch for one change on the way. At the time of writing (11 November 2026), Google says it intends to support the AIPREF shared training preference signal, written as a user-agent: __usage_ai-training rule, in early 2027. Your Google-Extended rule stays valid today, and you can add the new line when Google confirms it is live.
Ask your host or a developer for help if robots.txt returns a 5xx you cannot explain, or a security tool keeps blocking the Googlebot test.
The one message worth forwarding
Copy this to whoever looks after your site:
"Hi, could you update our robots.txt at the site root? Please keep Googlebot, Bingbot, Applebot and OAI-SearchBot allowed, and add a group with User-agent: Google-Extended, User-agent: Applebot-Extended and User-agent: GPTBot followed by Disallow: /. Any folder rules we have for everyone also need to go inside the search crawler group, because Google only follows its most specific group. Before you change anything, copy the current file to robots.txt.bak. Afterwards, please check that https://example.com/robots.txt returns 200 with text/plain, that a curl test with the Googlebot user agent returns 200 for the home page, and request a recrawl in the Search Console robots.txt report. If we use Cloudflare, leave the Search policy on allow. Thanks!"
Block the training names, never the search names, and test with curl before you walk away. If appearing as a grounded source in Gemini matters to you, weigh that goal before disallowing Google-Extended.
Reader questions
Will disallowing Google-Extended hurt my Google rankings?
No. Google says Google-Extended does not impact a site's inclusion in Google Search and is not used as a ranking signal in Google Search.
Does disallowing a page in robots.txt remove it from Google search results?
No. Google says robots.txt is not a mechanism for keeping a page out of Google, and a disallowed URL can still be indexed if other sites link to it. Use a noindex tag or password protection instead.
Can I stay in ChatGPT search but opt out of OpenAI training?
Yes. Allow OAI-SearchBot and disallow GPTBot. OpenAI says each setting is independent of the others.
Does Applebot-Extended crawl my website?
No. Apple says Applebot-Extended does not crawl webpages. It only tells Apple how it may use data that Applebot already crawled.
How long do robots.txt changes take to apply?
Google generally caches robots.txt for up to 24 hours, and you can speed it up with Request a recrawl in the Search Console robots.txt report. OpenAI says its systems can take about 24 hours to adjust.
What happens if my robots.txt file returns a server error?
RFC 9309 says crawlers must assume complete disallow when the file is unreachable with a 5xx error. Google says it stops crawling the site for the first 12 hours while it retries, so fix server errors quickly.
Does robots.txt legally stop AI companies from using my content?
RFC 9309 says robots.txt rules are not a form of access authorization; they are a request that well-behaved crawlers follow. This is general information, not legal advice.
Was this guide helpful?
Help us make the next update better.
Sources & further reading
- RFC 9309: Robots Exclusion Protocol
- Google: Common crawlers (Googlebot, Google-Extended)
- Google: How Google interprets the robots.txt specification
- Google: Update your robots.txt file
- Search Console Help: robots.txt report
- Apple: About Applebot
- OpenAI: Overview of OpenAI crawlers
- Cloudflare: AI Crawler and Agent access policies
- Cloudflare: robots.txt setting (Bot Preference Sync)
- Search Engine Journal: Cloudflare lets sites disallow AI training without blocking Googlebot (15 Sept 2026)
What changed
Added original article media and clarified the Google-Extended grounding tradeoff while preserving the distinction between search crawling and training controls.
Originally published . About our editorial updates.